 Fastero Dev Team
The Gemini API is billed per token: a price per million tokens you send (input) and per million tokens the model writes (output), thinking included. Below is every current Gemini text model's price on 12 November 2026, the discounts for batch, flex and cached input, what the free tier covers, what Google Search grounding adds, and a worked monthly bill next to Claude and OpenAI. Two price rises are already scheduled, so check the dates.
The short answer: per million input and output tokens on the paid tier, Gemini 4 Carbon and Gemini 4 Argon cost $2 and $10 through 30 November 2026, then $4 and $20 from 1 December. Gemini 4 Hydrogen, released on 12 November, costs $1.50 and $7.50. Gemini 3.8 Flash costs $0.75 and $3.75 through 31 December 2026, then $1.50 and $7.50. The cheapest models open to new developers are Gemini 3.5 Flash-Lite at $0.30 and $2.50 and Gemini 3.1 Flash-Lite at $0.25 and $1.50. The Batch API and Flex tier halve input and output prices; Priority costs 1.8 times as much. Cached input on Gemini 4 costs 5% of fresh input, applied automatically. The free tier covers Hydrogen and the Flash models but not Carbon or Argon, and Google uses free-tier content to improve its products. Grounding with Google Search gives 5,000 free searches a month across Gemini 3 and newer models, then $14 per 1,000. Checked 12 November 2026.
Fastero
Connect your database. Ask questions. Get dashboards.
Postgres, BigQuery, Snowflake, and 10+ sources — live-connected, AI-powered, no dashboard builder learning curve.
Try free →Gemini API prices (12 November 2026)
Dollars per million tokens, paid tier, standard (interactive) requests. All of these models take up to 1,048,576 input tokens.
| Model | Input | Output | Batch input / output | Cached input | Free tier |
|---|---|---|---|---|---|
| Gemini 4 Carbon | $2, then $4 from 1 Dec | $10, then $20 | $1 / $5, then $2 / $10 | $0.10, then $0.20 | No |
| Gemini 4 Argon | $2, then $4 from 1 Dec | $10, then $20 | $1 / $5, then $2 / $10 | $0.10, then $0.20 | No |
| Gemini 4 Hydrogen | $1.50 | $7.50 | $0.75 / $3.75 | $0.075 | Yes |
| Gemini 3.8 Flash | $0.75, then $1.50 from 1 Jan 2027 | $3.75, then $7.50 | $0.375 / $1.875, then $0.75 / $3.75 | $0.075, then $0.15 | Yes |
| Gemini 3.6 Flash | $0.75, then $1.50 from 1 Jan 2027 | $3.75, then $7.50 | $0.375 / $1.875, then $0.75 / $3.75 | $0.075, then $0.15 | Yes |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 | $0.15 / $1.25 | $0.03 | Yes |
| Gemini 3.1 Flash-Lite | $0.25 ($0.50 audio) | $1.50 | $0.125 / $0.75 | $0.025 | Yes |
| Gemini 3.1 Pro Preview | $2 ($4 over 200K) | $12 ($18 over 200K) | $1 / $6 | $0.20 ($0.40) | No |
| Gemini 3 Flash Preview | $0.50 ($1 audio) | $3 | $0.25 / $1.50 | $0.05 | Yes |
| Gemini 2.5 Pro* | $1.25 ($2.50 over 200K) | $10 ($15 over 200K) | $0.625 / $5 | $0.125 | Yes |
| Gemini 2.5 Flash* | $0.30 ($1 audio) | $2.50 | $0.15 / $1.25 | $0.03 | Yes |
| Gemini 2.5 Flash-Lite* | $0.10 ($0.30 audio) | $0.40 | $0.05 / $0.20 | $0.01 | Yes |
* Limited to developers who already used them. gemini-2.5-pro and gemini-2.5-flash are deprecated, and from 1 December 2026 requests to them route automatically to Gemini 3.8 Flash and Gemini 3.5 Flash-Lite. gemini-3.7-flash already routes to 3.8 Flash.
What the prices mean in practice:
- Input is everything you send on every call: instructions, history, files, tool results. In an agent loop it usually outweighs output.
- Output includes thinking. Google's column is "Output price (including thinking tokens)", so a higher thinking level costs more per answer.
- Hidden tokens count too. For Carbon and Argon, "Every token the model processes is counted and billed, including thinking tokens and internal tool system instructions and function declarations when using grounding."
- Price per token isn't price per task. A cheap model that needs three attempts can cost more than a dear one that needs one.
Gemini 4 models write text only. Images come from Nano Banana 2.1 (about $0.0336 per 1K image), embeddings from Gemini Embedding 2 ($0.20 per million text tokens), and Gemma 4 is free-tier only.
Long-context pricing tiers
Only Gemini 3.1 Pro Preview and Gemini 2.5 Pro charge more for prompts above 200,000 tokens. Gemini 4 and the Flash models list one price for the whole 1M-token window. The other labs don't: OpenAI's GPT-6.1 Sol doubles its input price above 272,000 tokens ($2 to $4), and Claude Haiku 5.5 goes from $0.10 to $0.50 above 100,000.
Context caching
Implicit caching "is enabled by default for all Gemini 2.5 and newer models": when a request starts with the same tokens as a recent one, the repeated part is billed at the cached price. Nothing to set up. Three rules decide whether you get it:
- Minimum size: 4,096 tokens on Gemini 4, 3.8 Flash, 3.6 Flash and 3.1 Pro Preview; 2,048 on Gemini 2.5 Flash and Pro.
- Order matters: "putting large and common contents at the beginning of your prompt" raises the hit rate.
- Agent loops on Gemini 4: "Gemini caches the full previous request only if the new request adds at least 2,050 tokens". Smaller additions re-process the last 2,050 tokens at the standard rate.
Explicit caching (creating a cache object yourself) isn't supported on Gemini 4. On Gemini 3 and 2.5 models it adds a storage charge per million tokens per hour: $0.50 on 3.8 Flash (rising to $1.00 on 1 January 2027), $1.00 on 3.5 Flash-Lite and $4.50 on 3.1 Pro Preview.
Batch, Flex, Priority and Contributor
| Tier | Price against standard | The trade-off | Status |
|---|---|---|---|
| Batch API | 50% | Asynchronous; "The target turnaround time is 24 hours" | generateContent API only |
| Flex | 50% | Synchronous, but "variable latency and best-effort availability" | Preview |
| Priority | 1.8x (Hydrogen: $2.70 and $13.50) | Served before standard and Flex traffic; its own rate limit, 0.3x standard | Preview |
| Contributor | "up to 50% off" on select models | Your data is used to improve Google's products and train models | Invite-only private preview |
The Gemini API free tier
The free tier needs no billing account. Checked 12 November 2026:
- Free: Gemini 4 Hydrogen, 3.8 Flash, 3.6 Flash, 3.5 Flash-Lite, 3.1 Flash-Lite, 3 Flash Preview, the 2.5 models for existing users, the embedding models and Gemma 4.
- Not free: Gemini 4 Carbon and Argon, Gemini 3.1 Pro Preview and the Nano Banana image models.
- Your data: free-tier content is used to improve Google's products; paid-tier content isn't.
- No Search grounding on most Gemini 3 and newer models.
- Limits: not printed per model on Google's rate-limit page; AI Studio shows them per project, and daily limits reset "at midnight Pacific time".
Paid usage moves through tiers as you spend:
| Usage tier | How you qualify | Billing cap | Spend limit per 10 minutes |
|---|---|---|---|
| Free | An active project | N/A | N/A |
| Tier 1 | Link a billing account | $250 | $10 |
| Tier 2 | Paid $100, 3 days after first payment | $2,000 | $200 |
| Tier 3 | Paid $1,000, 30 days after first payment | $20,000 - $100,000+ | $200 |
Two gotchas: since March 2026, Gemini API usage is excluded from the $300 Google Cloud free trial, and Google AI Studio itself stays free "unless users link a paid API key".
Grounding with Google Search
| Models | Free allowance | Then |
|---|---|---|
| Gemini 3 and newer | 5,000 search requests a month, shared across these models | $14 per 1,000 search requests |
| Gemini 2.5 | 1,500 requests a day (500 a day on the free tier, Flash and Flash-Lite) | $35 per 1,000 grounded prompts |
On Gemini 3 and newer you pay per search query, not per prompt: "A customer-submitted request to Gemini may result in one or more queries to Google Search." There's also a default cap of 1,500 grounded requests a day per project on the Gemini Developer API; Google points high-volume users to Vertex AI. Grounding with Google Maps has the same 5,000-a-month allowance and $14 rate on Gemini 3 and newer. Code execution and URL context cost only the tokens they add.
Connect any database. Ask in plain English.
Start free →Worked example: an agent's monthly bill
Take a coding or data agent that runs 1,000 sessions a month, each sending 40,000 input tokens and getting 6,000 back: 40 million input and 6 million output tokens. The cached column assumes three quarters of the input hits the cache, which needs a long shared prefix.
| Model | Standard | 75% of input cached | Batch |
|---|---|---|---|
| Gemini 4 Argon or Carbon, until 30 Nov | $140 | $83 | $70 |
| Gemini 4 Argon or Carbon, from 1 Dec | $280 | $166 | $140 |
| Gemini 4 Hydrogen | $105 | $62.25 | $52.50 |
| Gemini 3.8 Flash, until 31 Dec | $52.50 | $32.25 | $26.25 |
| Gemini 3.5 Flash-Lite | $27 | $18.90 | $13.50 |
How the Hydrogen line adds up: 40 x $1.50 = $60 of input plus 6 x $7.50 = $45 of output, $105. With caching, 30 million tokens at $0.075 ($2.25) plus 10 million at $1.50 ($15) plus the same $45 of output, $62.25. Add Search grounding on 20,000 queries a month and the first 5,000 are free; the other 15,000 cost $210.
Gemini vs Claude vs OpenAI API prices
Each lab's current models by price, per million input and output tokens, standard requests:
| Model | Lab | Input | Output |
|---|---|---|---|
| GPT-6 Astra | OpenAI | $10 | $50 |
| Claude Fable 5.2 | Anthropic | $8 | $40 |
| Claude Opus 5.5 | Anthropic | $4 | $20 |
| Gemini 4 Carbon / Argon (from 1 Dec) | $4 | $20 | |
| Gemini 4 Carbon / Argon (until 30 Nov) | $2 | $10 | |
| Claude Sonnet 5.5 | Anthropic | $2 | $10 |
| GPT-6.1 Sol | OpenAI | $2 | $10 |
| Gemini 4 Hydrogen | $1.50 | $7.50 | |
| Gemini 3.5 Flash-Lite | $0.30 | $2.50 | |
| Claude Haiku 5.5 (prompts up to 100K) | Anthropic | $0.10 | $0.50 |
| GPT-6 Luna | OpenAI | $0.10 | $0.50 |
All three labs halve prices for batch requests. On the worked example, Claude Sonnet 5.5 and GPT-6.1 Sol cost $140 a month, like Argon until 30 November, and Claude Opus 5.5 costs $280, like Argon from 1 December. Cached input is 5% of the input price on Gemini 4, Claude Opus 5.5 ($0.20 against $4) and GPT-6.1 Sol ($0.10 against $2). Google's edge is no long-context surcharge on Gemini 4. More in our Claude API pricing guide and Gemini vs Claude; if you use Gemini through a coding agent instead, see Google Antigravity and Gemini CLI.
When the cost numbers are for your team
A price table tells you what a token costs. Your team wants to know what it spent this week, on which model, and that needs usage logged and charted somewhere everyone can open. Fastero is an AI and data platform where people and AI agents work together on a team's data:
- A scheduled notebook. Keep your API key in Secrets, which reach notebook cells as environment variables, and run the notebook on a cron schedule, included on the Free plan.
- SQL next to Python. SQL cells run on your Postgres or BigQuery connection and land in Python as a pandas DataFrame; a SQL cell's result can become a dashboard widget.
- A dashboard that stays current. It refreshes on a timer or, for Postgres and BigQuery data, when the data changes. Viewers are free; Free has no end date and Pro is $20 per editor a month.
- Claude can build it through Fastero's MCP server; our Claude API pricing page shows a live price tracker Claude built in Fastero.
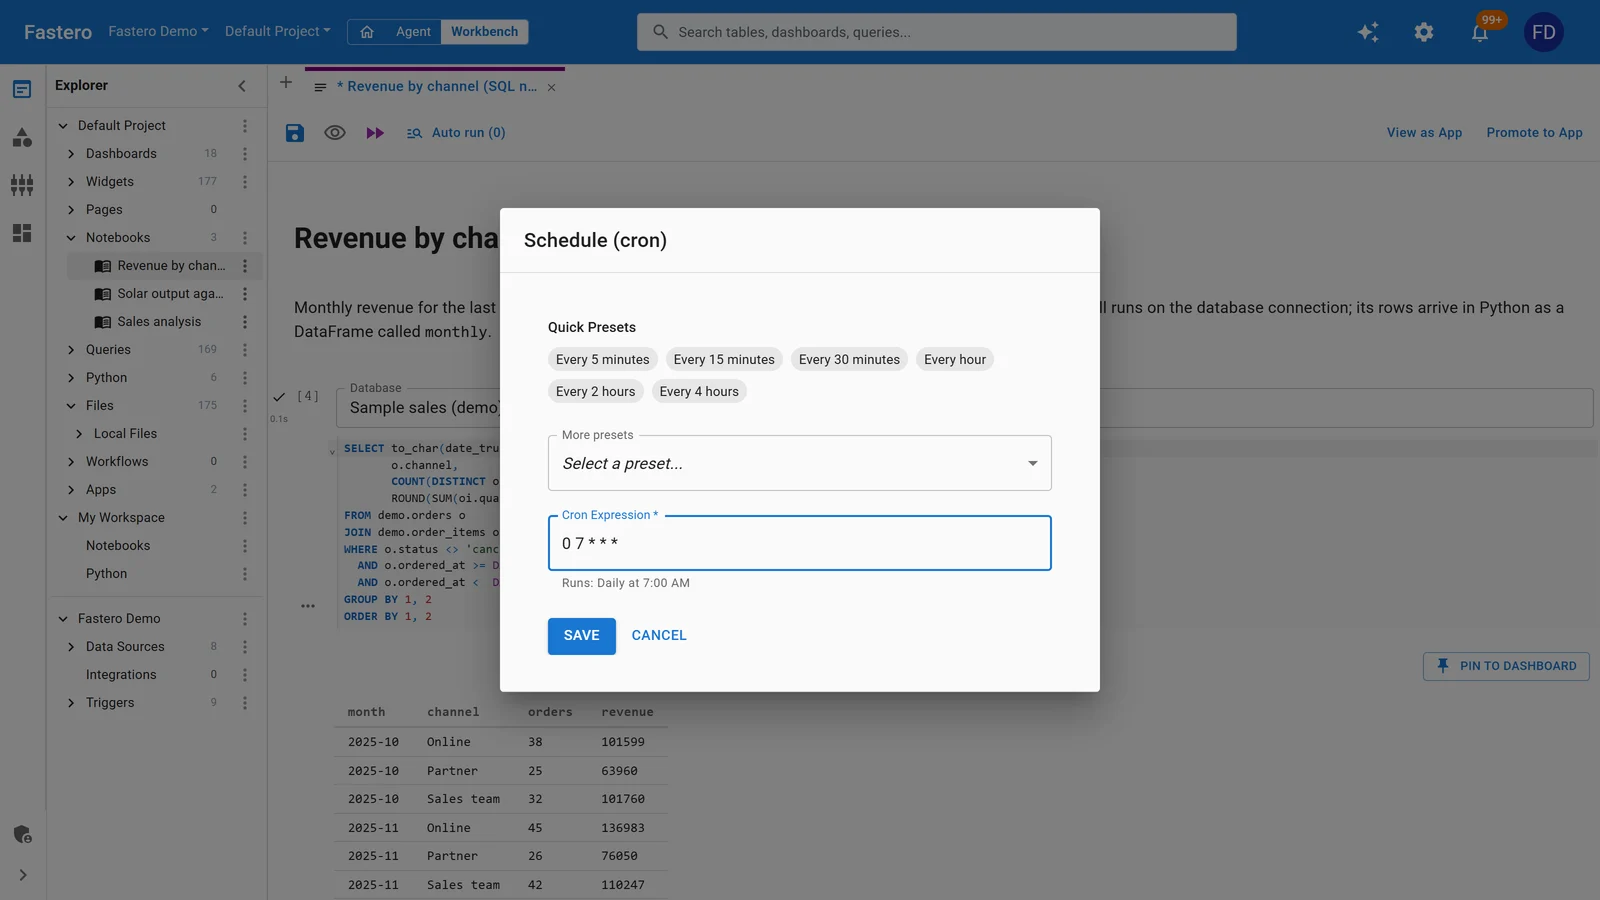
Scheduling a notebook in Fastero: presets or any cron expression. Sample data.
FAQ
How much does the Gemini API cost?
From $0.25 per million input tokens and $1.50 per million output tokens for Gemini 3.1 Flash-Lite to $2 and $10 for Gemini 4 Carbon and Argon, which rise to $4 and $20 on 1 December 2026. Gemini 4 Hydrogen costs $1.50 and $7.50. Batch requests cost half, checked 12 November 2026.
Is the Gemini API free?
There is a free tier with no billing account. It covers Gemini 4 Hydrogen and the Flash and Flash-Lite models, but not Carbon, Argon or 3.1 Pro Preview, and free-tier content is used to improve Google's products. Rate limits show per project in AI Studio.
Why is Gemini 4 Argon going up in price?
Google lists $2 and $10 per million tokens "through November 30, 2026" and $4 and $20 "starting December 1, 2026", for both Argon and Carbon. It gives no reason on the pricing page. Gemini 3.8 Flash and 3.6 Flash double on 1 January 2027.
How much does Grounding with Google Search cost?
On Gemini 3 and newer: 5,000 free search requests a month shared across those models, then $14 per 1,000, with a default cap of 1,500 a day per project. On Gemini 2.5: 1,500 free a day, then $35 per 1,000 grounded prompts.
Is Gemini cheaper than Claude and GPT?
At the top, yes: Gemini 4 Carbon costs less than Claude Fable 5.2 ($8 and $40) and GPT-6 Astra ($10 and $50), even after 1 December. In the middle, Gemini 4 Hydrogen ($1.50 and $7.50) undercuts Claude Sonnet 5.5 and GPT-6.1 Sol ($2 and $10). At the bottom, Claude Haiku 5.5 and GPT-6 Luna ($0.10 and $0.50) cost less than Gemini 3.5 and 3.1 Flash-Lite; only Gemini 2.5 Flash-Lite ($0.10 and $0.40), open to existing users only, is cheaper on output.
Sources
Checked 12 November 2026.
- Google AI for Developers: Gemini Developer API pricing, Models, Gemini 4 Carbon, Gemini 4 Argon, Gemini 4 Hydrogen, Gemini 3.8 Flash, Rate limits, Billing, Context caching, Batch API, Flex inference, Priority inference, Data logging and the Contributor Tier, Grounding with Google Search, Deprecations, Release notes
- Anthropic: Claude API pricing
- OpenAI: API pricing